Clean CRM Data for AI Agents: Data Quality Is the Bottleneck, Not the Model
Clean CRM data for AI agents is the fix when agents give bad answers about your CRM, because the cause is usually messy data, not a weak model. Duplicates, blank fields, inconsistent labels and mismatched owners hand agents conflicting facts that they act on confidently. Upgrading the model rarely helps. Cleaning the data, and keeping it clean, does.
Sales-led teams are adding agents for lead routing, account research, rep follow-up and pipeline reviews. Many of them hit the same wall within weeks: the agent works in the demo and then stumbles on real records. The model isn't what changed between the demo and production. The data is.
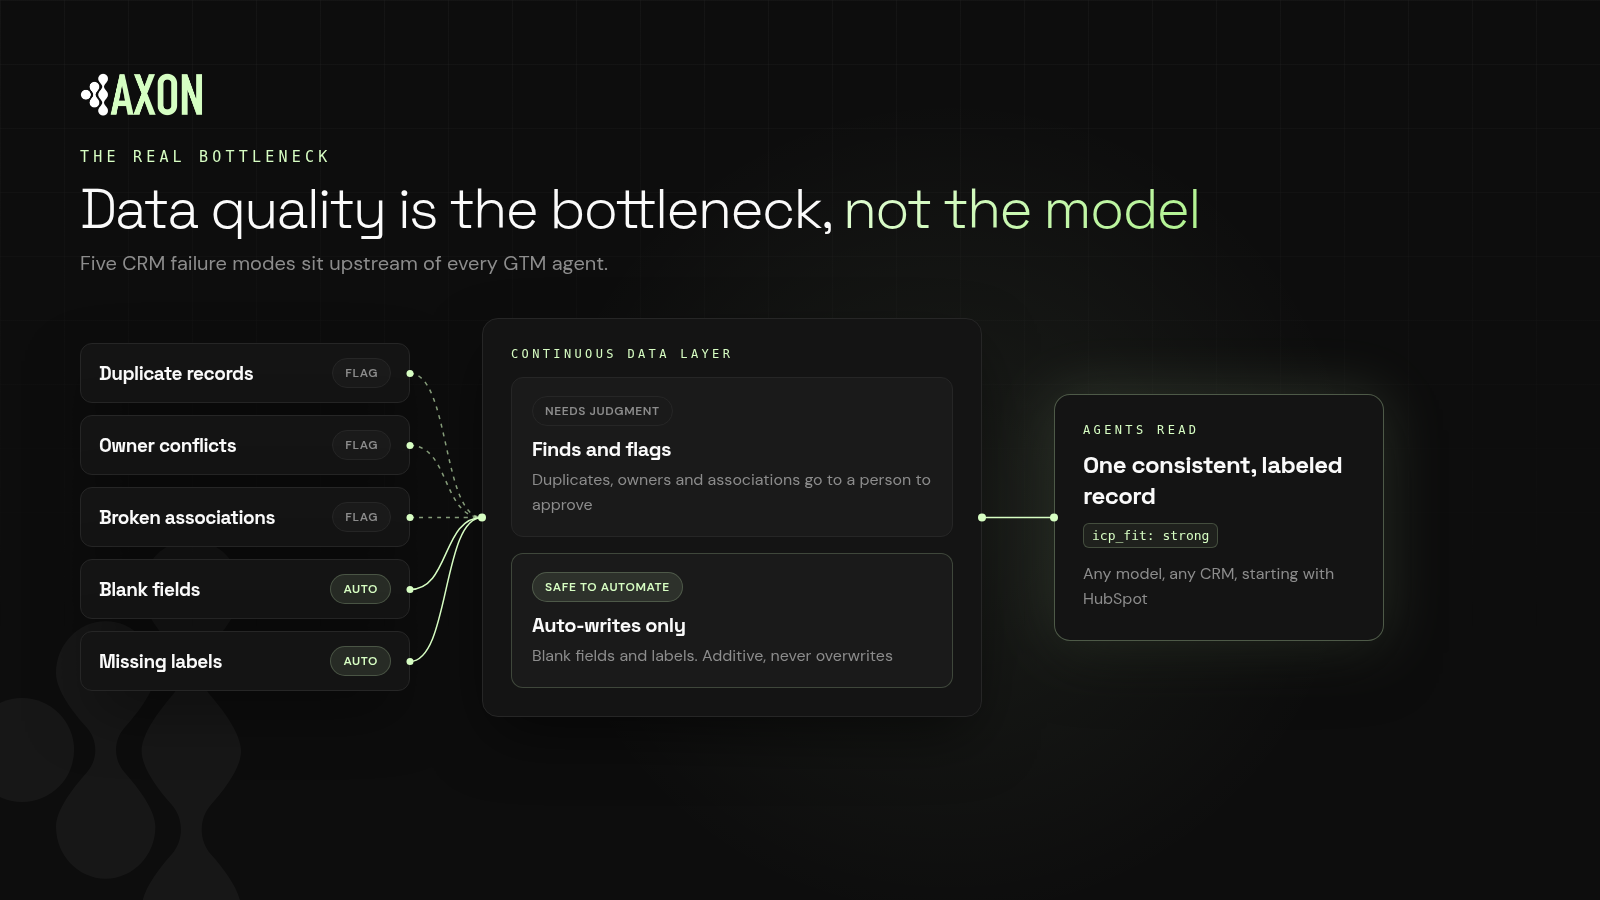
Figure: Five data-quality failure modes sit upstream of every sales agent. A continuous data layer finds and flags the issues that need judgment and fills only blank fields and labels, so agents read one consistent record.
What does clean CRM data for AI agents mean?
Definition: Clean CRM data for AI agents is CRM data where each entity appears once, the fields agents rely on are filled, each record carries a consistent label, and conflicts between related records are flagged before an agent reads them.
That's a higher standard than "clean enough for a dashboard," and it's the core of AI-ready CRM data. A report can absorb a few duplicates as rounding error. An agent can't. It acts on individual records, one at a time, and each bad record becomes a bad action.
Why isn't the AI model the bottleneck?
Models reason over what they're given
Key idea: An agent can't reason its way past a wrong fact. If the record says the wrong rep owns the account, the best model in the world will route to the wrong rep.
Modern models are strong at summarizing, classifying, and drafting. What they can't do is know which of two conflicting records is true, or invent a value that was never captured. Better reasoning over bad inputs produces more confident wrong answers.
Model upgrades are getting easier; data fixes aren't
Swapping one model for another is often a configuration change. Fixing years of duplicate companies, half-filled properties, and orphaned deals is not. That's why data quality, not model choice, is where most teams' agent projects stall.
Messy data also costs more to process
When records are duplicated and unlabeled, agents pull more context to compensate: extra records, extra activity history, extra fields to reconcile. That extra context costs time and compute, and it gives the agent more chances to pick the wrong fact. Clean, labeled records let an agent read a compact summary instead.
What CRM data problems break AI agents?
1. Duplicate records split the truth
Two records for the same company divide activity, owners, and deal history. An agent reading one sees half the story and may contact a customer as if they were a new prospect.
2. Blank fields force guesses
If industry, company size, or lifecycle stage is empty, an agent either guesses or skips the record. Guessing produces wrong personalization; skipping leaves good accounts untouched.
3. Missing labels cause inconsistent decisions
Without a shared label for ICP fit or segment, each agent re-derives it from raw fields, and different agents can reach different conclusions about the same account.
4. Owner conflicts misroute work
Definition: An owner conflict is a mismatch in ownership across related records, such as a contact owned by one rep while its company and open deal belong to another.
Agents that route, assign tasks, or draft handoffs depend on ownership. Conflicts send work to the wrong person and create awkward duplicate outreach.
5. Broken associations hide context
A deal without a company, or a contact without the deal they're active in, looks like an isolated record. Agents miss the relationship and act as if it doesn't exist.
How do you clean CRM data for AI agents and keep it clean?
Start with what agents read
Inventory the fields, labels, and associations each agent uses (our guide to filling blank fields in HubSpot walks through this). That list defines "clean" for your team, and it keeps you from boiling the ocean.
Automate only the additive changes
Filling a blank field or attaching a label doesn't overwrite anyone's work. These are safe to automate and they close the most gaps quickly.
Flag the changes that need judgment
Merging duplicates, changing owners, and repairing associations affect territories, compensation, and customer relationships. Find and flag them, give a person the context, and let them approve the fix.
Make it continuous, not a project
Key idea: Data quality is a process, not a project. A one-time cleanup starts decaying the day it ends.
New records arrive from forms, imports, integrations, and reps every day. A continuous layer checks them as they come in, so agents never read a backlog of new problems.
How does Axon Data clean CRM data for AI agents?
Axon Data is the AI transformation layer for revenue data. It works with any CRM, starting with HubSpot, and runs continuously between your CRM and the agents that depend on it.
- Finds and flags duplicates, owner conflicts, and broken associations, with the context a person needs to approve the right change.
- Only auto-writes blank fields and labels, so automation adds information without overwriting your team's work.
- Serves agents a consistent, labeled view of each record, so every workflow reads the same truth.
For example, a sales-led team running a follow-up agent on top of HubSpot would want duplicates and owner conflicts flagged before the agent ever drafts a message. That way, existing customers don't get treated like cold prospects, and leads reach the account executive who owns the account.
Want to see where your CRM stands today? Get a free CRM scan from Axon Data.
What else do people ask about clean CRM data for AI agents?
Is the model or the data the bigger problem for sales agents?
For most teams, it's the data. Models reason well over the facts they're given, but they can't resolve duplicates, fill missing values, or know which conflicting record is correct.
What makes CRM data "clean" for AI agents?
Each entity appears once, the fields agents rely on are filled, every record has a consistent label, and owner and association conflicts are flagged before agents act.
Can I just clean my CRM once before launching agents?
A one-time cleanup helps, but it decays quickly as new records flow in. Agents need data that's monitored continuously so new duplicates, blanks, and conflicts are caught as they appear.
Should duplicates and owner conflicts be fixed automatically?
These changes need human judgment because they affect territories and customer relationships. The safer approach is to find and flag them for approval and automate only additive changes like filling blank fields and adding labels.
Which CRMs does Axon Data work with?
Axon Data works with any CRM, starting with HubSpot, and runs continuously as a layer between your CRM and your agents.
See where your CRM stands today: duplicates, blank fields, owner conflicts and broken associations.
Get a free CRM scan